TL;DR
- Massive Scale, Free License: GLM-5.2 is a powerful 744B Mixture-of-Experts (MoE) model with a 1M context window, freely available under the MIT license but highly demanding on infrastructure.
- Steep Self-Hosting Costs: Deploying it requires immense VRAM (at least 12x H100 GPUs), translating to roughly ₹3,000/hour in raw compute costs from Indian data centers, excluding complex MLOps overhead.
- India Benchmarks Are Pending: Official Mumbai latency and performance metrics are not yet public; managed domestic endpoints like Simplismart are currently still in closed beta.
- Hidden Output Costs: The model "thinks out loud," averaging around 43,000 output tokens per task, meaning production budgets must be modeled on a per-task basis rather than just raw token rates.
- Verify GST/INR Billing Directly: Do not rely on USD-to-INR conversions for financial planning; Indian enterprises must verify native INR invoicing and GST/ITC compliance directly with their chosen provider.
If you are an AI engineer in India evaluating GLM-5.2 for production, you have probably encountered the same infrastructure hurdle everyone faces with a 744-billion-parameter open-weight model: the license is generous, but the cloud compute bill is not. Z.ai released GLM-5.2 under the MIT license, meaning no usage restrictions, no geographic limits, and complete freedom to fine-tune and self-host. That is exactly what makes the deployment strategy so interesting for Indian tech teams. You can run this model yourself. The real question is whether you should, and what it actually costs to deploy it properly for a Mumbai, Bengaluru or Hyderabad facing product.
This guide covers what is actually confirmed about GLM-5.2 today, why self-hosting GLM-5.2 in India is a harder challenge than the MIT license implies, and what a managed inference route through a platform like Simplismart looks like. This includes being upfront about which performance numbers are officially published right now, and which ones simply are not yet available.
GLM-5.2 Specifications: A Technical Recap
GLM-5.2 is Z.ai's (formerly Zhipu AI) flagship open-weight model, launched in June 2026 as the successor to GLM-5.1. The core specifications, confirmed on Z.ai's model card and mirrored across the major inference platforms hosting it, include:
- Architecture: A Mixture-of-Experts (MoE) transformer, with a total parameter count reported in the 744B–753B range depending on how you count shared experts and the multi-token-prediction head. Simplismart's own technical breakdown of the model cites ~753B total parameters; Fireworks' model listing shows 743B; most third-party trackers round to ~744B. All three are describing the same checkpoint, but the number that actually governs your serving cost is the active parameter count.
- Active parameters per token: ~40B. This is the MoE routing number that determines your real-time compute load, as opposed to the headline total that dictates your VRAM footprint.
- Context window: 1,048,576 tokens (1M) natively, roughly 5x GLM-5.1's ~200K window, with a maximum output of 131,072 tokens per response.
- License: MIT. Features open weights, no commercial-use restrictions, and is hosted on Hugging Face at zai-org/GLM-5.2.
- Architecture innovations: Z.ai's release notes highlight IndexShare, which reuses the same attention indexer across every four sparse layers, cutting per-token FLOPs by roughly 2.9x at a 1M context. It also features an improved MTP (multi-token prediction) layer for speculative decoding that increases acceptance length by up to 20%.
- Pre-training data: 28.5 trillion tokens.
- Thinking modes: Two configurable "thinking effort" levels, allowing you to trade reasoning depth against latency depending on whether you are serving an interactive product or a background batch job.
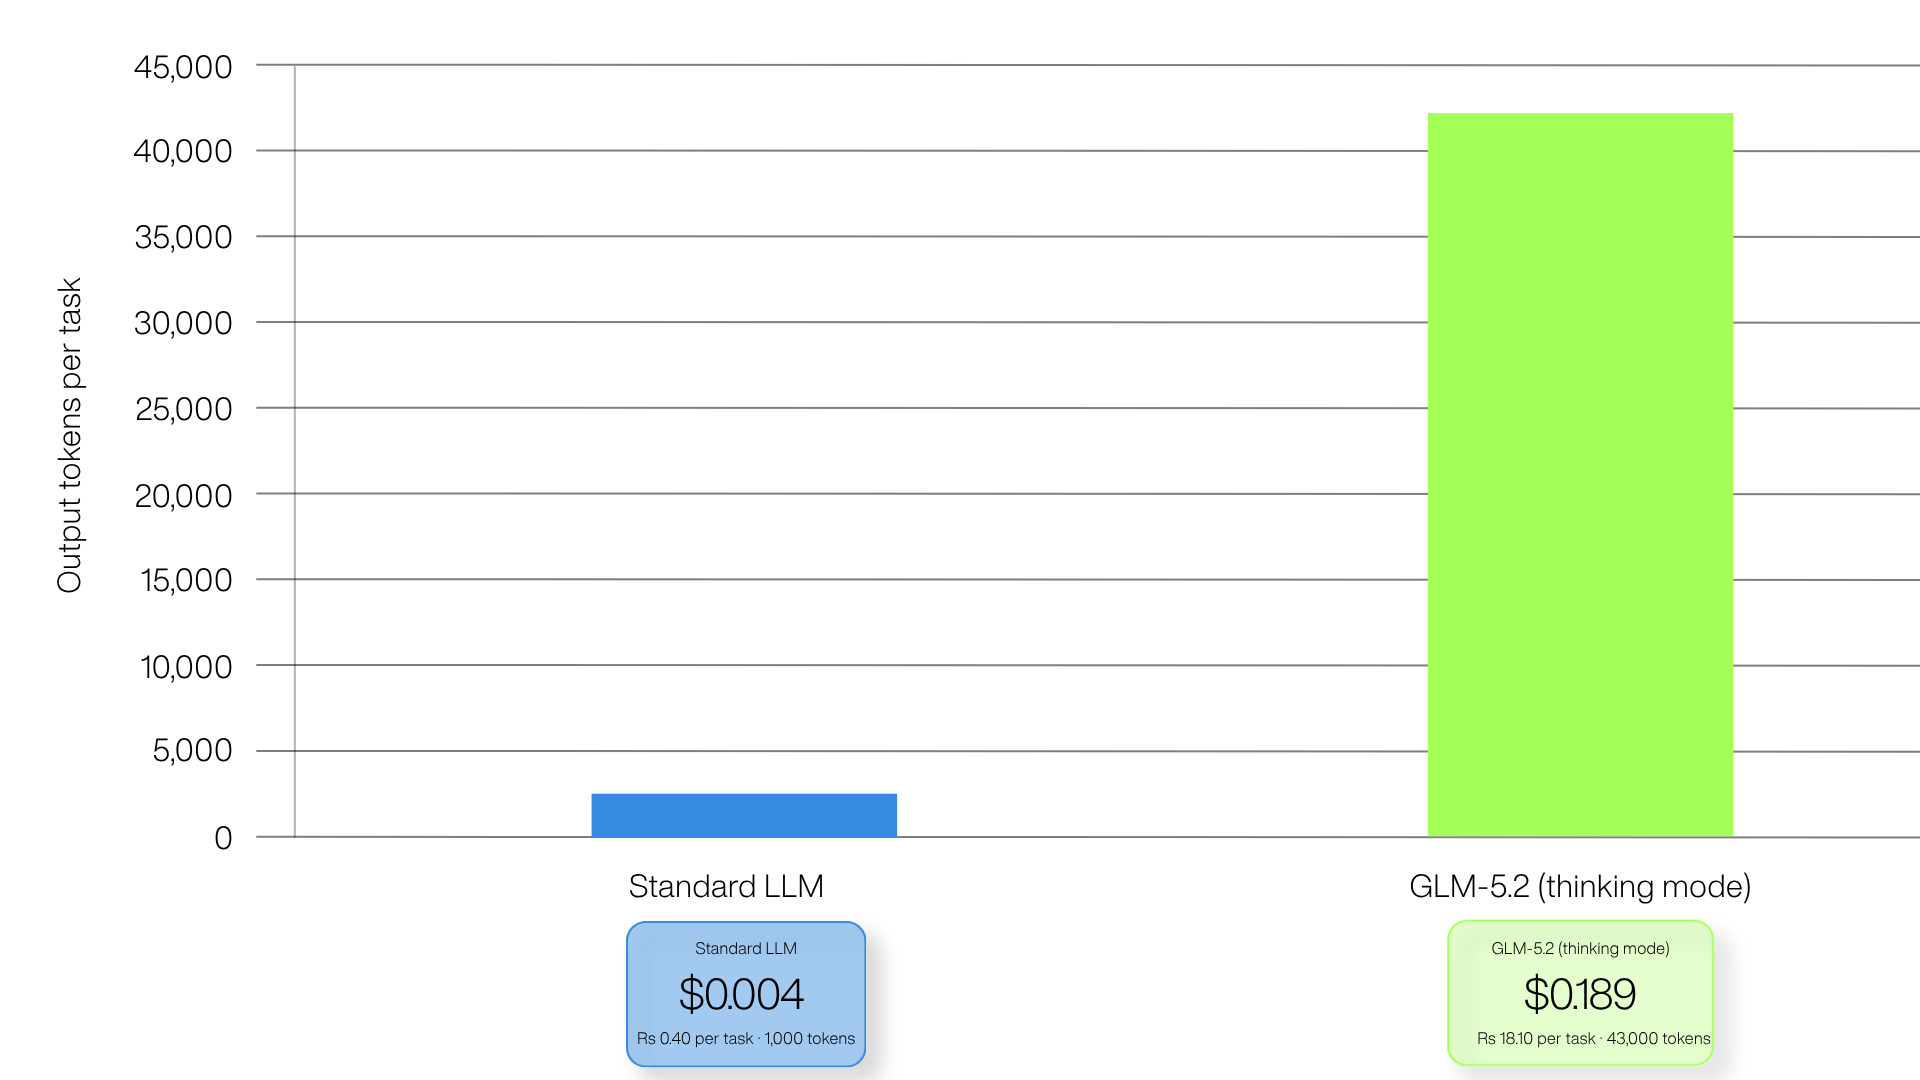
One crucial detail worth internalizing before you size any deployment: Artificial Analysis has noted that GLM-5.2 tends to use around 43,000 output tokens per task on average during its evaluation runs. For a model that is cheap per token, that habit of "thinking out loud" at length is exactly the kind of thing that turns a good per-token price into a mediocre per-task cost. This generation behavior matters just as much for your total INR budget as the headline API rate does.
Why Self-Hosting GLM-5.2 in India is Genuinely Expensive
The MIT license removes the legal barrier to self-hosting GLM-5.2. It does nothing about the physics.
The VRAM Problem Before India-Specific Constraints
The VRAM problem starts before you even get to India-specific deployment constraints. At native BF16 precision (2 bytes/parameter), the ~753B-parameter checkpoint requires roughly 1.5 TB of weight storage. Quantizing to FP8 halves that to around 753 GB, still well beyond what fits on a single node of consumer or even most enterprise GPUs.
Add the KV cache required to actually use the model's headline feature, the 1M-token context window, and the footprint grows further: roughly 160 GB of additional VRAM for BF16 KV cache at full context, or ~80 GB at FP8.
Factor in activations and runtime overhead, and a realistic production serving footprint at long context lands around 830–950 GB. This means a minimum of 12x H100 (80GB) or 8x H200 (141GB) GPUs just to serve the model with headroom, before you have even handled multi-node orchestration, tensor/pipeline parallelism, or a serving stack tuned for MoE routing.
That is before you factor in what those GPUs actually cost to rent in the Indian market.
GPU Availability and H100 Rental Costs in India
H100s are available domestically through Indian cloud providers. E2E Networks, for instance, lists on-demand H100 pricing on its own site at ₹249/hour per GPU as of this writing, with an 8x H100 configuration running ₹1,995/hour, and multi-month commitment pricing dropping as low as ₹155.90/hour per GPU for large-scale, longer-term deployments. E2E's H100 capacity is available out of Bangalore and Mumbai data centres specifically, which matters significantly if data residency within India is part of your calculus.
Run the arithmetic on the low end of what GLM-5.2 actually needs: 12x H100 at E2E's on-demand rate, and you are looking at roughly ₹2,988/hour just in GPU rental, before power, networking, storage for the model weights, or engineering time.
That is before you have handled the harder part: MoE routing at production scale, KV cache management across a 1M-token context window, quantization tuning that does not degrade reasoning quality, and a serving stack (vLLM, SGLang, TensorRT-LLM, or similar) tuned specifically for this architecture. None of that is as simple as "rent GPUs, run vLLM, done"; it is a complex systems problem that a dedicated MLOps team solves once and re-solves every time the model architecture changes.
The Hidden Operational Overhead of Managed Inference
Operational overhead is the part that does not show up in a standard GPU-hour calculator. Multi-node coordination for a model this size typically requires tensor and pipeline parallelism with high-bandwidth interconnect just to hold latency steady.
Quantization scheme choices materially change the quality/latency tradeoff, especially for long-context and tool-use workloads. Because GLM-5.2's average output length runs long, cost modeling without guardrails can produce benchmark wins that are genuinely expensive to serve in production.
For an engineering team whose core product is not inference infrastructure, that is a massive amount of specialized effort to stand up and maintain. This is precisely the case for routing through a managed inference layer instead of owning the GPU fleet outright.
Benchmarks: What is Actually Published for GLM-5.2 Right Now
Here is where it pays to be straightforward: a lot of comparison content in the generative AI space quietly invents performance numbers that sound authoritative but are unverified.
At the time of writing, there is no officially published benchmark table comparing an India-hosted GLM-5.2 endpoint against a US-hosted endpoint. There are also no published Time-to-First-Token (TTFT), token throughput, or P99 latency figures broken out by Indian cities, not from Simplismart, not from Z.ai, nor from any other inference provider serving the model.
GLM-5.2 is currently running in closed beta on Simplismart's platform (confirmed on Simplismart's own GLM-5.2 technical breakdown, last updated June 22, 2026), with general availability scheduled in the coming days. It is not yet listed on Simplismart's public model marketplace or pricing page alongside models like DeepSeek-V3, Llama 3.3 70B, or Qwen2.5 72B.
Confirmed Global Benchmarks Worth Grounding In
Here are the officially verified benchmark figures to evaluate:
- Artificial Analysis Intelligence Index (v4.1): GLM-5.2 ranks #1 among open-weight models at a score of 51–53 (depending on the evaluation window), placing ahead of MiniMax-M3 (44), DeepSeek V4 Pro (44), and Kimi K2.6 (43).
- GDPval-AA v2: GLM-5.2 scores 1524, which Artificial Analysis positions as directly competitive with GPT-5.5 running at extra-high reasoning effort (1514), serving as a proprietary reference point rather than an India-specific comparison.
- Fireworks AI Deployment: Fireworks AI's model catalog lists GLM-5.2 as "Ready" for serverless deployment with function calling and a 1,040K-token context window. Artificial Analysis provider tracking highlights Fireworks serving GLM-5.2 among its fastest and most intelligent hosted models, though this reflects global/US serverless performance rather than an India-region breakdown.
Evaluating Mumbai Latency for Production Workloads
If your evaluation genuinely depends on P99 latency from Mumbai versus a US region, as it should if you are building real-time voice AI agents or latency-sensitive applications for Indian users, the only reliable path right now is to benchmark directly against your own traffic patterns once GLM-5.2 reaches General Availability on Simplismart, or request a customized proof-of-concept from their team.
Publishing an estimated city-by-city latency breakdown without hard telemetry data manufactures false precision that falls apart under real-world testing.
GLM-5.2 INR Pricing: What is Confirmed vs. Currency Conversions
Simplismart's public pricing catalog quotes all listed models, including DeepSeek-R1, DeepSeek-V3, Llama 3.1 405B, and Qwen2.5 72B, exclusively in USD on a per-1M-token basis for LLM serving, alongside dedicated GPU-hour rates (ranging from $1.20/hour for an NVIDIA T4 up to $5.20/hour for an H200).
There is currently no INR toggle or dedicated India-specific price sheet on the public portal. Because GLM-5.2 remains in closed beta, access is managed directly through Simplismart's enterprise team.
Estimated Pricing Breakdown (USD to INR Reference)
To establish an accurate baseline, we can look at the officially published rates on Fireworks AI's serverless platform:
*INR conversions are calculated at an approximate USD/INR mid-market exchange rate of ~₹95.7 (late August 2026 reference; subject to market fluctuations). This represents an estimated budgeting conversion rather than an officially billed INR price from either platform.
Essential Cost-Modeling Considerations for Indian Teams
- Provider-Specific Rates: These figures reflect Fireworks AI's specific pricing tier. Direct API rates from Z.ai or alternative serverless providers may vary and should be checked individually.
- Per-Task Output Overhead: Remember the ~43,000 average output-tokens-per-task metric. At $4.40 / 1M output tokens, verbose reasoning and agentic workflows can quickly inflate production expenses beyond initial per-token estimates. Always model your costs per complete task rather than relying solely on raw token rates.
- GST-Compliant Invoicing: A simple currency conversion does not equate to a GST-compliant, INR-denominated invoice. If your finance team requires local Indian tax compliance and input tax credit (ITC), discuss enterprise billing structures directly with Simplismart's sales team upon GA.
- Forex Volatility Protection: With USD/INR fluctuations ranging between ~₹90 and ~₹97 over the past year, locking in native INR billing through an India-based infrastructure partner provides critical predictability over holding variable USD-denominated compute commitments.
GST Invoicing and Compliance for Indian Companies
This is an area where clarity and accuracy are critical, especially since compliance details are often misrepresented or assumed in third-party content.
Currently, there is no officially published documentation from Simplismart detailing its exact Goods and Services Tax (GST) invoice formatting, specific HSN/SAC classification codes, or the precise CGST/SGST versus IGST split across accounts. While common for rapidly scaling cloud platforms, this means those specific line-item mechanics should not be assumed.
General GST Invoicing Framework for Indian Tech Teams
For enterprise planning and tax compliance, keep the following foundational guidelines in mind while confirming specifics directly with Simplismart's billing team:
- Mandatory Tax Invoice Requirements: Under the Indian GST framework, any registered domestic service provider billing an Indian entity must issue a valid tax invoice. This invoice must display the GSTIN of both parties, the applicable HSN/SAC code, the taxable value, and the corresponding tax breakdown, either CGST + SGST for intra-state transactions or IGST for inter-state billing (standard for centralized cloud platforms).
- Input Tax Credit (ITC) Reconciliation: To successfully claim Input Tax Credit without reconciliation delays, your corporate billing address and registered GSTIN on file must match perfectly with your tax filings.
- Startup India & BFSI Requirements: If your organization holds DPIIT / Startup India recognition or operates under strict sector-specific compliance mandates (such as fintech and BFSI), confirm invoicing terms with Simplismart’s sales team beforehand. Specifically, verify how invoices are categorized for your entity type and whether native INR invoicing is supported on your tier.
- Requesting Sample Invoices: If your finance or procurement team requires formal verification prior to contract execution, the recommended approach is to request a sample invoice directly from Simplismart rather than relying on unverified third-party estimates.
Who Should Deploy GLM-5.2 in India (And Who Should Wait)?
Taking into account the model’s benchmark performance, domestic self-hosting hardware costs, and the managed beta deployment landscape, here is an objective breakdown of target use cases:
1. Indian Voice AI and Conversational AI Startups
If your product architecture is fundamentally latency-sensitive (e.g., real-time transcription, conversational voice agents, interactive customer support), the argument for a managed India endpoint goes beyond raw token pricing.
Deploying and maintaining an optimized, low-TTFT multi-node serving cluster across 12+ enterprise GPUs for a 744B MoE architecture requires extensive, ongoing MLOps resources. Running direct latency benchmarks against an India-based endpoint once GLM-5.2 reaches General Availability (GA) on Simplismart provides a much clearer operational ROI.
2. BFSI and Regulated Teams with Strict Data Residency Mandates
If your governance and compliance policies mandate that inference workloads, not merely data storage, must remain physically within Indian borders, evaluate domestic GPU infrastructure (such as E2E Networks data centers in Mumbai and Bangalore) or managed platforms offering sovereign India-hosted endpoints.
Engaging directly with Simplismart’s team regarding their localized India infrastructure roadmap will provide far more actionable clarity than speculative third-party benchmarks.
3. Product Teams Needing Low Latency Without Owning GPU Clusters
If your capacity planning indicates that a dedicated 8–12 GPU footprint is disproportionately high for your current production traffic, a managed serverless or dedicated endpoint serves as a viable middle ground. You retain the full flexibility of an MIT-licensed model without bearing the ongoing burden of multi-node infrastructure orchestration.
When Does Self-Hosting or Waiting Make More Sense?
- Asynchronous / Latency-Insensitive Tasks: If your workloads are batch-oriented, low-volume, or tolerant of standard international transit latencies.
- Existing In-House MoE Infrastructure: If your engineering team already possesses dedicated GPU clusters and specialized MLOps expertise in Mixture-of-Experts (MoE) orchestration, KV cache optimization, and custom quantization.
- High-Volume Cost Crossover: At massive, sustained token volumes, dedicated GPU instances (either through Simplismart's BYOC tier or direct domestic cloud providers like E2E Networks) can become more cost-effective per token than serverless options. This threshold should be modeled using actual task length and traffic distribution.
he Honest Bottom Line on GLM-5.2 in India
GLM-5.2 stands out as a highly capable, MIT-licensed open-weight model with a 1M-token context window that expands the possibilities for large-codebase analysis and complex document processing.
While self-hosting in India is technically feasible through domestic cloud providers at competitive rates, the high VRAM demands, KV cache expansion, and multi-node orchestration represent significant ongoing operational overhead. Managed inference platforms exist specifically to abstract away that complexity.
Because GLM-5.2 is currently in closed beta on Simplismart, public city-level latency benchmarks and official INR pricing sheets are not yet published. For engineering and product teams evaluating production deployments, the most reliable next step is to contact Simplismart directly for beta priority access, conduct empirical latency tests against your own traffic shapes, and verify customized INR/GST invoicing structures for your business.
Frequently Asked Questions (FAQ)
What are the core technical specifications and license of GLM-5.2?
GLM-5.2 is an open-weight Mixture-of-Experts (MoE) model released by Z.ai under the permissive MIT license. It features a total parameter count between 744B and 753B with ~40B active parameters per token. The model comes with a native 1,048,576-token (1M) context window, a maximum output of 131,072 tokens per response, and was pre-trained on 28.5 trillion tokens.
What GPU hardware is required to self-host GLM-5.2 in production?
Because GLM-5.2 requires roughly 1.5 TB of storage in BF16 and ~753 GB in FP8, plus additional VRAM for the 1M-token KV cache and runtime overhead, a realistic production serving footprint ranges from 830 GB to 950 GB of VRAM. This necessitates a cluster of at least 12x NVIDIA H100 (80GB) or 8x NVIDIA H200 (141GB) GPUs with high-bandwidth interconnects to manage multi-node orchestration and MoE routing.
How much does it cost to rent GPUs for GLM-5.2 in India?
Domestic cloud providers like E2E Networks offer H100 instances in Bangalore and Mumbai data centers starting at roughly ₹249/hour per GPU on-demand (or ₹1,995/hour for an 8x H100 node). Renting the minimum required cluster of 12x H100 GPUs starts at approximately ₹2,988/hour in raw compute costs, excluding power, networking, model storage, and ongoing MLOps engineering overhead.
Are there official GLM-5.2 latency benchmarks available for Mumbai or Bangalore?
No. Currently, there are no officially published Time-to-First-Token (TTFT), throughput, or P99 latency benchmarks broken out specifically for Indian cities or comparing an India-hosted endpoint against US regions. While GLM-5.2 is in closed beta on platforms like Simplismart, engineering teams building latency-critical apps (such as voice AI) are advised to run empirical tests against their own traffic patterns during beta evaluation.
What is the estimated API pricing for GLM-5.2 in Indian Rupees (INR)?
While neither Simplismart nor Z.ai currently quotes an official native INR rate on public pricing sheets, based on Fireworks AI's published serverless pricing and an exchange rate of ~₹95.7 per USD, the estimated costs are:
- Input Tokens: $1.40 / 1M tokens (~₹134 / 1M tokens)
- Cached Input: $0.14 / 1M tokens (~₹13.40 / 1M tokens)
- Output Tokens: $4.40 / 1M tokens (~₹421 / 1M tokens)
Why does GLM-5.2's output token generation significantly affect production budgets?
According to evaluations by Artificial Analysis, GLM-5.2 averages approximately 43,000 output tokens per task due to its extended reasoning ("thinking out loud") behavior. Because output tokens are priced higher ($ 4.40/1 M tokens), verbose agentic workflows can quickly drive up per-task costs. Engineering teams should model expenses per completed end-to-end task rather than relying solely on base per-token rates.
How can Indian enterprises ensure GST compliance and claim Input Tax Credit (ITC) for GLM-5.2 inference?
Under India’s GST framework, domestic B2B transactions require valid tax invoices detailing the GSTIN of both entities, appropriate HSN/SAC codes, and the correct tax breakdown (CGST + SGST for intra-state or IGST for inter-state billing). Because custom platform invoicing terms may vary, companies, particularly in BFSI or DPIIT-registered startups, should request a sample invoice directly from the provider's sales team before signing enterprise contracts.
Ready to Deploy GLM-5.2 Without the Multi-Node Complexity?
Skip the heavy operational overhead of configuring multi-node H100 clusters, managing complex MoE routing, and absorbing unpredictable infrastructure costs. Whether you are building real-time conversational agents or processing massive context documents, Simplismart offers high-performance inference solutions tailored for Indian engineering teams.
- Frictionless Scale: Access high-throughput managed endpoints for massive frontier models like GLM-5.2 without managing underlying cluster orchestration.
- Optimized Latency: Leverage production-ready infrastructure designed to handle long-context windows and intensive agentic workloads efficiently.
- Flexible Deployment: Scale smoothly from pay-as-you-go serverless access to dedicated enterprise private clusters configured for your exact production requirements.
Explore Simplismart Inference & Get Beta Priority Access Today