Key Takeaways
- Natively Multilingual (201 Languages): Build low-latency, code-mixed voice and chatbots in Indian regional languages without relying on slow English-translation workarounds.
- Zero-OCR Document Processing: Built-in vision capabilities allow direct ingestion of scanned vernacular paperwork, government forms, and invoices.
- 27B is Dense, Not Sparse: Unlike its Mixture-of-Experts (MoE) siblings, Qwen3.5-27B is a fully dense model, ensuring predictable token latency and stable single-GPU serverless deployments.
- Test Your Own Latency: Don't trust generic benchmarks for Hindi vs. English Time-to-First-Token (TTFT). Non-Latin tokenization overhead means you must test on your specific inference stack.
- Factor in Landed INR Costs: Public USD rate cards omit the 27B model and ignore Indian tax laws. Always request custom commercial quotes and add the mandatory 18% OIDAR GST to calculate true deployment costs.
For Indian tech teams building multilingual voice agents, WhatsApp support bots, or document processing pipelines, model selection inevitably comes down to two critical factors: proficiency in local languages and the ability to run on serverless infrastructure without costs or latency spiraling out of control.
Alibaba introduced Qwen3.5 on February 16, 2026, followed by its mid-size checkpoints, including the 27B dense model, on February 24. This article examines Qwen3.5’s true multilingual capabilities, the viability of deploying its 27B variant in serverless environments, and the actual cost of running it from India, based strictly on official data from Qwen, Together AI, and Indian tax authorities.
What Is Qwen3.5? Alibaba’s Multimodal Heavyweight
Qwen3.5 is Alibaba's newest open-weight model family, released under the permissive Apache 2.0 license. During its launch, Alibaba heavily positioned the model for the "agentic AI era". Compared to its predecessor, Qwen3.5 is reportedly 60% cheaper to run and up to 8x better at processing large workloads. Crucially, it introduces "visual agentic capabilities", allowing the model to operate desktop and mobile applications directly.
The model family rolled out in carefully staged releases:
- February 16, 2026: The flagship Qwen3.5-397B-A17B dropped. This massive Mixture-of-Experts (MoE) model features 397 billion total parameters, with 17 billion active during any given forward pass.
- February 24, 2026: Mid-size checkpoints were released, including Qwen3.5-122B-A10B, Qwen3.5-35B-A3B, and the highly anticipated Qwen3.5-27B.
- March 2, 2026: Smaller edge variants arrived, rounding out the family with 9B, 4B, 2B, and 0.8B models.
(Note: All release specifications are officially documented on the QwenLM GitHub repository and their Hugging Face model cards.)
Two Architectural Details You Cannot Ignore
If you are building pipelines or agents on top of Qwen3.5, two foundational upgrades define what the model can do:
- Native Multimodality (Early Fusion): Qwen3.5 uses what the official documentation calls a "Unified Vision-Language Foundation." Because it underwent early fusion training on multimodal tokens, every checkpoint in the family, including the lightweight 27B model, is a vision-language model right out of the box. Why it matters: If your document-processing pipeline needs to read scanned Hindi or Tamil invoices as images rather than clean text, Qwen3.5 handles it natively without requiring you to bolt on a separate OCR or vision model.
- Massive Context Window: The native context length is 262,144 tokens, which can be extended to just over 1 million tokens using YaRN scaling. Why it matters: For processing endless customer support transcripts or multi-turn document reviews, Qwen3.5 provides a working window large enough to ingest entire codebases or rulebooks at once.
The Multilingual Story: The "201 Languages" Clarification
A lot of secondary tech coverage repeats a "140+ languages" figure when discussing recent Qwen releases. That number is outdated.
According to Qwen's official GitHub repository and Hugging Face model cards, Qwen3.5 explicitly states: "Global Linguistic Coverage: Expanded support to 201 languages and dialects." This claim is identical across every Qwen3.5 model card (from 0.8B up to 397B), proving it is a family-wide capability, not a typo on a single checkpoint.
For context, the predecessor (Qwen3) officially supported 119 languages. The true generational leap is from 119 to 201 languages.
Evaluating Indian Languages: Look at the Aggregate Scores
Qwen has not published a separate, itemized list confirming that Hindi, Bengali, Tamil, and Telugu are explicitly named among the 201. Instead, they published a set of aggregate multilingual benchmark scores for Qwen3.5-27B.
Here is what the official numbers actually look like:
The Honest Takeaway for AI Builders
These scores are averages across dozens of languages. Qwen does not publish isolated scores for Hindi, Bengali, Tamil, or Telugu in its official materials.
If a client asks for "Qwen3.5's exact Hindi benchmark score," the accurate answer is that an isolated figure does not exist. What does exist is an incredibly strong aggregate performance across 29 to 55 languages, and given the 201-language footprint, major Indian languages are virtually guaranteed to be in that mix. Warning: Any blog post citing a hyper-specific "Hindi accuracy: 91.2%" for Qwen3.5 is citing fabricated data.
Finally, to put this in perspective: Qwen3.5-27B scored an 82.2 on MMLU-ProX. Its massive predecessor, Qwen3-235B-A22B, scored only a 77.9. The fact that a 27B model beats a 235B model proves that Qwen3.5's multilingual gains come from vastly improved training methodology and data quality, not just raw parameter bloat.
Why Qwen3.5 Matters for Indian AI Products
Building AI applications for the Indian market comes with unique linguistic and technical challenges. While Alibaba did not design Qwen3.5 exclusively for India, its architectural profile directly addresses three primary use cases in the Indian ecosystem:
1. Low-Latency Multilingual Voice Agents
A voice bot handling customer interactions in Hindi, Marathi, or Tamil must converse naturally within the native language. Traditional "translate-to-English, infer, and translate back" architectures introduce unacceptable round-trip latency and strip away vital regional phrasing, honorifics, and context. Qwen3.5's native multilingual coverage allows teams to run a single, end-to-end conversational loop without translation intermediaries.
2. Code-Mixed Customer Support Bots
Indian users rarely type in textbook vernacular; queries routinely blend languages within a single sentence (e.g., "mera order kab aayega, tracking number bhi nahi mila"). Because Qwen3.5 was trained across 201 languages and dialects, it handles spontaneous code-switching (like Hinglish, Tanglish, or Benglish) far more natively than models trained predominantly on English and CJK datasets.
3. Vernacular Document Processing (OCR-Free Pipelines)
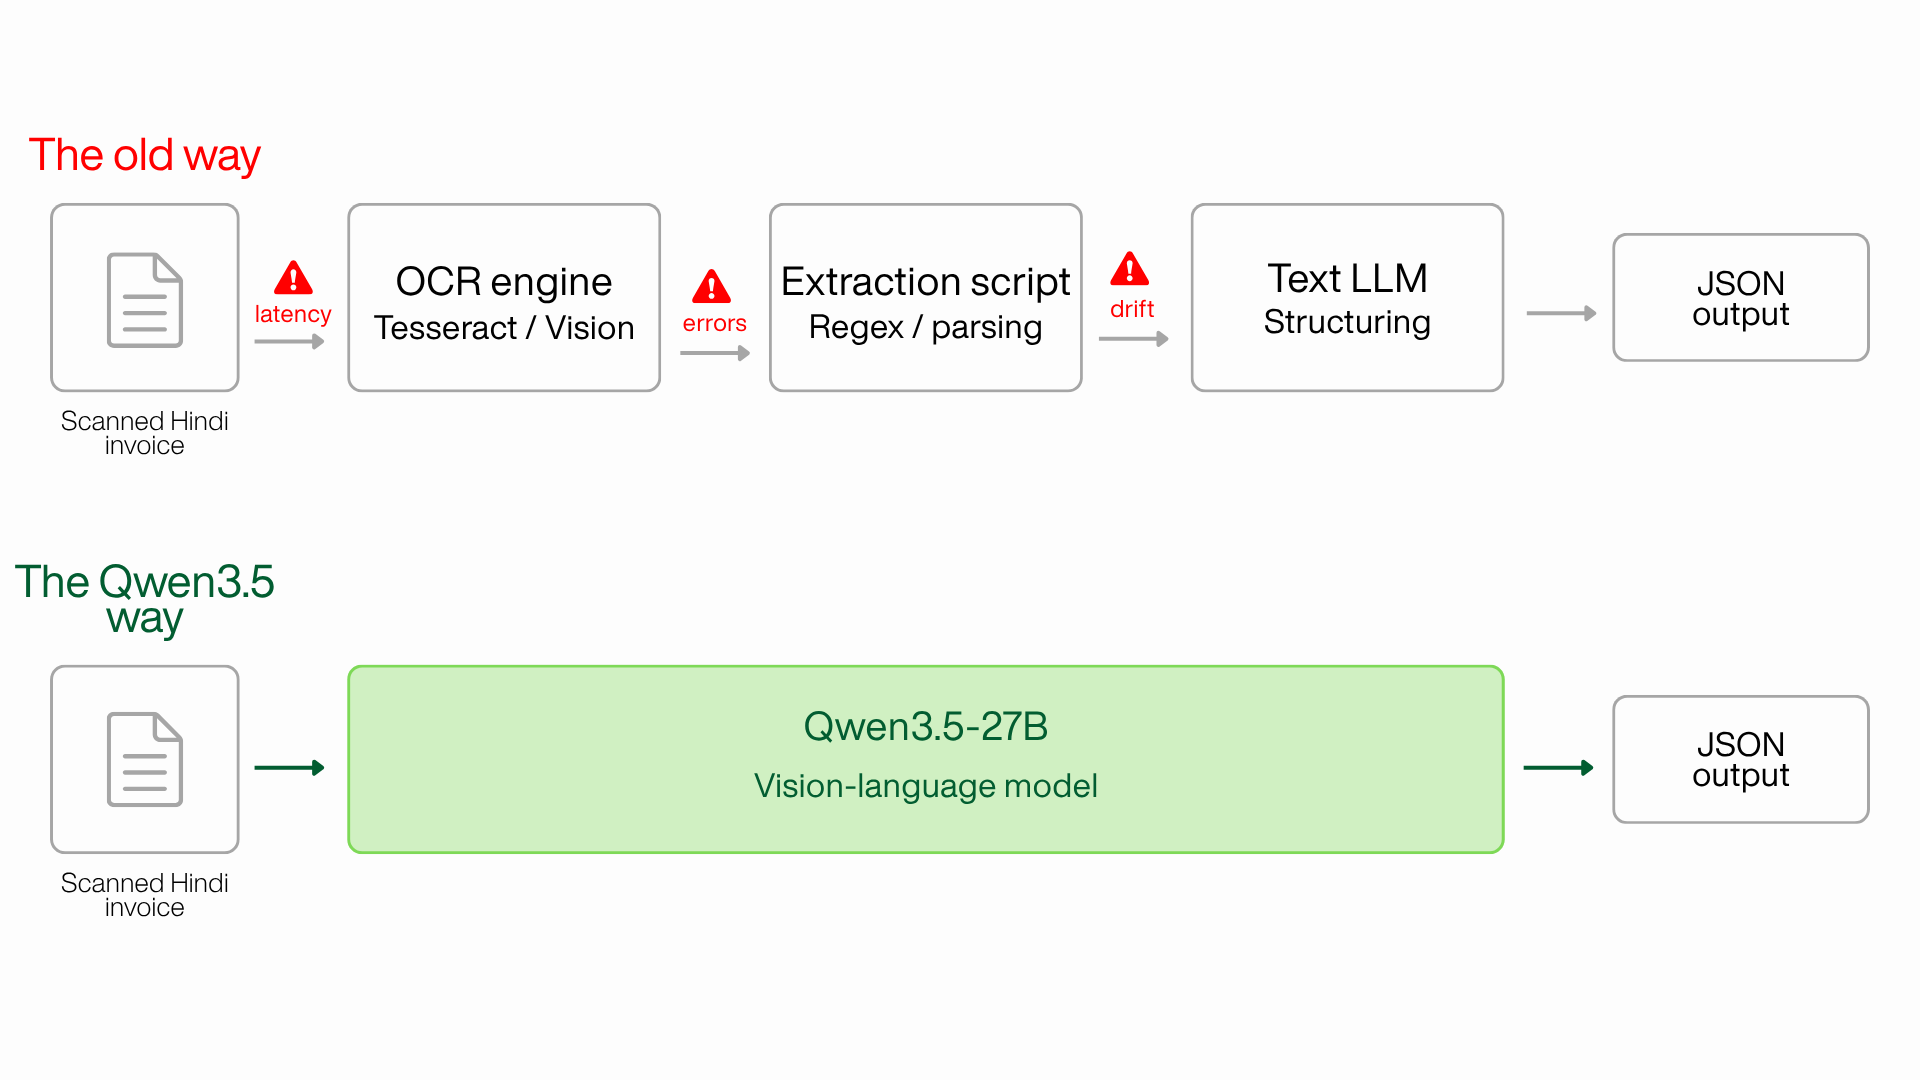
Because Qwen3.5 is natively vision-language out of the box, scanned regional paperwork, such as state government forms, land records, and local GST invoices, can be ingested directly as images. This eliminates the need for brittle, multi-stage pipelines (OCR → Text Extraction → LLM), significantly lowering engineering complexity and per-document processing overhead.
Serverless Inference Fit: Debunking the 27B Architecture Myth
There is a common misconception in technical summaries claiming that “Qwen3.5-27B has low active parameters for efficient batching.”
This is factually incorrect.
According to Qwen's official model cards, Qwen3.5-27B is a fully dense model.
Qwen uses a clear naming convention: its Mixture-of-Experts (MoE) checkpoints carry an -AxxB suffix denoting total versus active parameters per forward pass (e.g., 397B-A17B, 122B-A10B, and 35B-A3B). The 27B checkpoint has no such suffix, meaning all 27 billion parameters are active on every token.
MoE Checkpoints (Sparse): Qwen3.5-397B-A17B | Qwen3.5-122B-A10B | Qwen3.5-35B-A3B
Dense Checkpoints: Qwen3.5-27B | Qwen3.5-9B | Qwen3.5-4B
Why the 27B Dense Model Excels on Serverless Endpoints
Even without MoE sparsity, the 27B variant offers concrete operational advantages for serverless and multi-tenant inference:
- Predictable Per-Token Compute: On MoE architectures, dynamic expert routing introduces minor latency variance across requests. A dense model eliminates this, making token pricing, batch scheduling, and continuous batching much easier to forecast on shared infrastructure.
- Manageable Memory Footprint: At standard BF16 precision, the base model weights consume roughly 54GB (27B×2 bytes). With Qwen's official FP8 and GPTQ-Int4 checkpoints, this footprint drops significantly, fitting cleanly on a single 80GB GPU (such as an NVIDIA A100 or H100) with abundant headroom for the Key-Value (KV) cache during high-concurrency bursts.
- Optimal Quality-to-Compute Ratio: Despite having fewer total parameters, Qwen3.5-27B matches or slightly outperforms the 35B-A3B MoE checkpoint across key reasoning and translation benchmarks:
- MMLU-Pro: 86.1 (27B Dense) vs. 85.3 (35B-A3B MoE)
- GPQA Diamond: 85.5 (27B Dense) vs. 84.2 (35B-A3B MoE)
- WMT24++: 77.6 (27B Dense) vs. 76.3 (35B-A3B MoE)
- MMLU-Pro: 86.1 (27B Dense) vs. 85.3 (35B-A3B MoE)
Key Architecture Decision: If your sole engineering goal is minimizing active parameter compute during high-throughput batch runs, the Qwen3.5-35B-A3B (3B active) is the appropriate sparse fit. If you need consistent latency, simple single-GPU deployment, and maximum output quality per GPU-hour, the Qwen3.5-27B Dense model is the better production choice.
Latency From India: What Is Actually Verifiable?
A common request when evaluating models for the Indian market is a direct Time-to-First-Token (TTFT) comparison between Hindi and English inputs, benchmarked from an India-based client.
The truth: No official, published figure exists for this. Neither Qwen, Together AI, nor Alibaba Cloud publishes a generic "Hindi vs. English TTFT" metric. This is because TTFT is not a fixed property of the model; it is a downstream measurement dictated by your specific serving stack, geographic region, GPU tier, quantization method, and concurrent load.
However, based on Qwen's official documentation, here is how the mechanics actually work:
- Prompt Processing Dictates TTFT: Time-to-first-token is primarily a function of prompt processing time, which scales with the total number of input tokens.
- The Non-Latin Script Tax: Tokenizer efficiency varies drastically by script. Because most subword vocabularies are built on Latin-dominated training corpora, non-Latin scripts (like Devanagari, Bengali, Tamil, and Telugu) typically require more tokens to represent the same number of characters compared to English.
- Qwen's Massive Vocabulary Advantage: The official model card states that Qwen3.5-27B features a padded vocabulary size of 248,320 tokens. A vocabulary this large generally improves tokenization efficiency for non-English languages compared to smaller tokenizers. However, Qwen has not published a direct token-count comparison table for identical Hindi vs. English sentences.
The Honest Engineering Recommendation: Do not trust arbitrary latency numbers in blog posts. The only defensible benchmark is one you run yourself. Set up a same-day test sending matched-length Hindi and English prompts to your serverless endpoint (e.g., Simplismart) and log the TTFT from an India-based client. This yields a real number specific to your exact batching and quantization settings.
Serverless Pricing in INR: What Is Published, What Isn’t
Evaluating the commercial viability of a model requires looking at landed costs, not just base USD figures. Based on official pricing catalogs, here is the current landscape.
Together AI’s Published USD Rates
As of this writing, Together AI’s official serverless pricing page lists per-token rates for only two Qwen3.5 checkpoints:
Notice what is missing? The Qwen3.5-27B does not appear on Together AI's public serverless rate card. While it may be available via dedicated or provisioned instances (which are quote-based), any public article citing a specific, fixed Together AI serverless price for the 27B is referencing unpublished data.
Calculating the True INR Landed Cost
To calculate the true cost for an Indian business, you must account for two factors:
- Forex Rate: Using a baseline of ₹95.2 per USD (based on historical Fed/Wise data for August 26, 2026).
- Indian Tax Law (GST): Under India’s GST framework, cloud compute and SaaS services fall under OIDAR (Online Information and Database Access or Retrieval). These services attract a flat 18% GST, confirmed by current CBIC guidelines. Note: This assumes reverse-charge liability for a GST-registered Indian business importing a B2B service (per Section 5(3) of the GST Act). This is standard, mandatory compliance, not an optional add-on.
Here is what the actual landed INR cost looks like for the officially priced Together AI models:
The Simplismart Ecosystem
If you are evaluating Simplismart, note that their public pricing model is structured around Bring-Your-Own-Cloud (BYOC), custom on-premises deployments, and custom infrastructure sizing. They do not publish a generic per-token rate card for shared serverless endpoints. To get an apples-to-apples comparison against Together AI, you must engage their sales team for a custom quote.
The Bottom Line for Buyers
Based strictly on verifiable public data, running Qwen’s flagship 397B-A17B MoE costs roughly 3.5x more on input and 14x more on output compared to the 9B model. Because neither Together AI nor Simplismart currently lists a fixed public serverless rate for the dense 27B variant, procurement teams must secure direct commercial quotes rather than relying on third-party estimates.
Production Code: Multilingual Inference with Dynamic Language Routing
Below is a production-ready implementation demonstrating how to interact with Qwen3.5-27B via standard OpenAI-compatible endpoints (such as those hosted via vLLM, SGLang, or dedicated inference providers).
This pipeline integrates a lightweight client-side language-detection step to dynamically route localized system prompts before invoking the model.
Key Implementation Details:
- Pre-Inference Language Routing: By detecting the language upstream using ISO 639-1 codes, you can steer the assistant’s persona and honorific style in the user's native tongue without adding latency.
- Official Sampling Parameters: Configured according to Qwen3.5's recommended settings for non-thinking/instruct tasks (temperature=0.7, top_p=0.8, presence_penalty=1.5, top_k=20).
- Thinking Mode Control: Sets "enable_thinking": False in chat_template_kwargs to prioritize low latency for real-time customer support queues.
Python
import os
from langdetect import detect
from openai import OpenAI
# Initialize client using standard OpenAI-compatible environment variables
# (OPENAI_BASE_URL points to your vLLM, SGLang, or serverless endpoint)
client = OpenAI(
base_url=os.getenv("OPENAI_BASE_URL", "http://localhost:8000/v1"),
api_key=os.getenv("OPENAI_API_KEY", "EMPTY"),
)
def detect_language(text: str) -> str:
"""Best-effort language code detection (ISO 639-1)."""
try:
return detect(text)
except Exception:
return "en"
def build_system_prompt(lang_code: str) -> str:
""" Returns a native-language system prompt based on detected language."""
prompts = {
"hi": "आप एक सहायक हैं। हिंदी में स्पष्ट और संक्षिप्त उत्तर दें।",
"bn": "আপনি একজন সহায়ক সহকারী। বাংলায় স্পষ্ট এবং সংক্ষিপ্ত উত্তর দিন।",
"ta": "நீங்கள் ஒரு உதவிகரமான உதவியாளர். தமிழில் தெளிவாகவும் சுருக்கமாகவும் பதிலளிக்கவும்.",
"te": "మీరు సహాయకరమైన సహాయకుడు. తెలుగులో స్పష్టంగా మరియు సంక్షిప్తంగా సమాధానం ఇవ్వండి.",
}
return prompts.get(
lang_code,
"You are a helpful assistant. Respond clearly and concisely.",
)
def multilingual_chat(user_message: str) -> str:
"""Routes user queries through dynamic system prompting and standard Qwen3.5 sampling."""
lang = detect_language(user_message)
system_prompt = build_system_prompt(lang)
messages = [
{"role": "system", "content": system_prompt},
{"role": "user", "content": user_message},
]
# Sampling parameters based on Qwen3.5 official guidance for general instruct tasks
response = client.chat.completions.create(
model="Qwen/Qwen3.5-27B",
messages=messages,
max_tokens=32768,
temperature=0.7,
top_p=0.8,
presence_penalty=1.5,
extra_body={
"top_k": 20,
"chat_template_kwargs": {"enable_thinking": False},
},
)
return response.choices[0].message.content
# --- Demonstration: Multilingual Support Queue ---
if __name__ == "__main__":
queries = [
"मेरा ऑर्डर कब आएगा?", # Hindi
"আমার রিফান্ড এখনও আসেনি।", # Bengali
"என் பேமெண்ட் தோல்வியடைந்தது, என்ன செய்வது?", # Tamil
"What is the status of my complaint?", # English
]
for q in queries:
print(f"Query: {q}")
print(f"Response: {multilingual_chat(q)}")
print("-" * 50)
Conclusion: Building with Qwen3.5 in the Indian Market
For Indian engineering teams, model selection is rarely just about raw English reasoning benchmarks. It requires a delicate balance of vernacular proficiency, architectural simplicity, and predictable landed costs. Qwen3.5, and specifically the 27B dense checkpoint, offers a highly compelling answer to these unique market challenges.
By bringing native vision-language capabilities and a massive 201-language training footprint to a manageable 54GB weight class, Qwen3.5 allows you to strip away latency-heavy workarounds like OCR-to-text extraction or translate-and-infer loops. It enables you to build faster, more natural voice and chat agents that actually understand code-switching and regional scripts natively.
As you move toward production, keep these final takeaways in mind:
- Understand your architecture: The 27B model wins on single-GPU quality and predictable continuous batching precisely because it is a dense model, not a sparse MoE. Plan your serverless endpoints accordingly.
- Trust your own benchmarks: Do not rely on unverified third-party claims for Hindi-vs-English TTFT (Time-to-First-Token). Use the routing code provided above to build a quick prototype and measure latency on your exact serving stack.
- Calculate true landed costs: Always factor in India's 18% OIDAR GST and current forex rates. Because major providers do not currently list public serverless pricing for the 27B variant, secure direct commercial quotes rather than extrapolating from 9B or 397B rate cards.
Ultimately, Alibaba did not design Qwen3.5 explicitly as an "India-only" model, but its foundational architectural choices make it one of the most capable, cost-effective, and practical open-weight models for solving the hardest problems in the Indian AI ecosystem today.
Frequently Asked Questions (FAQs)
Does Qwen3.5 officially support Indian languages like Hindi, Bengali, and Tamil?
Yes. Qwen3.5 expanded its linguistic coverage to 201 languages and dialects across all checkpoints (up from 119 in Qwen3). While Alibaba does not publish isolated, single-language benchmark scores for individual Indic languages, the model demonstrates strong aggregate multilingual performance (such as an 82.2 on MMLU-ProX) and natively handles code-switching (like Hinglish or Tanglish) without translation round-trips.
Is Qwen3.5-27B a Mixture-of-Experts (MoE) or a dense model?
Qwen3.5-27B is a fully dense model. Unlike its sparse MoE siblings (which use the -AxxB suffix, such as 35B-A3B or 397B-A17B), all 27 billion parameters in the 27B model participate in every forward pass. This makes its per-token compute predictable and well-suited for single-GPU serverless setups using FP8 or INT4 quantization.
Do I need a separate OCR pipeline to process vernacular Indian documents?
No. Every checkpoint in the Qwen3.5 family is natively multimodal out of the box using a Unified Vision-Language Foundation. You can pass scanned regional paperwork, invoices, or handwritten forms directly into the model as images, bypassing the latency and maintenance overhead of a separate OCR-to-text pipeline.
What is the exact Time-to-First-Token (TTFT) latency for Hindi vs. English?
There are no official, vendor-published TTFT numbers for Hindi versus English. TTFT depends heavily on prompt tokenization, serving framework (vLLM/SGLang), quantization, and GPU location. Because non-Latin scripts typically use more tokens per character, you should run a direct benchmark with matched prompts on your specific deployment stack to measure actual latency from India.
How do Indian taxes (GST) apply to serverless LLM API costs?
Cloud compute and inference APIs imported from foreign providers (like Together AI) fall under OIDAR (Online Information and Database Access or Retrieval) services. Indian businesses importing these services under B2B compliance must account for a mandatory 18% GST under the reverse-charge mechanism (Section 5(3) of the GST Act) on top of the base USD-to-INR converted rate.
Ready to Deploy Qwen3.5 in Production?
Stop guessing about token latency, infrastructure overhead, and hidden deployment costs.
If your team is building multilingual voice agents or high-throughput document pipelines for the Indian market, Simplismart.ai provides the production-grade infrastructure you need. From predictable serverless endpoints to custom Bring-Your-Own-Cloud (BYOC) deployments, Simplismart is engineered to help Indian AI teams scale open-weight models efficiently and cost-effectively.
Talk to our experts today to get a custom quote and benchmark Qwen3.5 on your exact stack.